I once audited a small e-commerce site that had added almost 400 new product pages. The owner was convinced he had a penalty, because traffic was flat while his catalog kept growing. In my experience, a penalty is rarely the answer. Within five minutes I found the real culprit: his XML sitemap listed only 60 URLs. Google had no roadmap to the other 340 pages. We rebuilt the sitemap, resubmitted it, and crawl coverage doubled within two weeks. Traffic followed about a month later.
Your XML sitemap is the clearest signal you can hand a search engine about which pages matter on your site. When it is broken, stale, or missing pages, you are asking Google to guess. I include a sitemap validation in every monthly seo website check I run, because it catches indexation problems before they show up in traffic reports. In this guide I will show you how to check XML sitemap errors the way I do on client sites: locate the file, validate it, cross-check it against your real pages, confirm the robots.txt reference, and fix whatever you find. The whole process takes under thirty minutes and every method is free.
What an XML Sitemap Actually Does (and Why Errors Cost You Traffic)
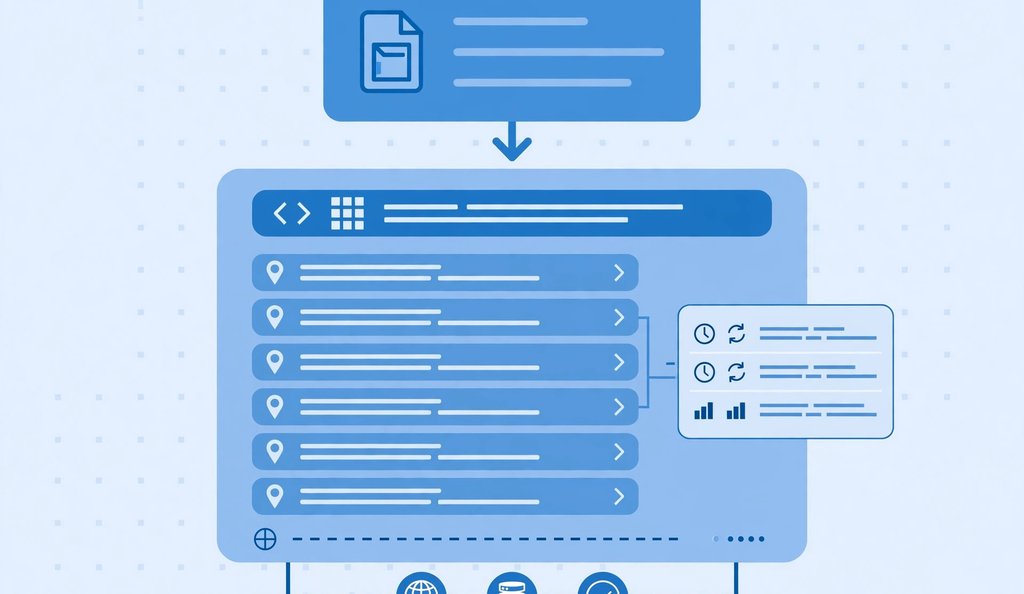
An XML sitemap is a structured file, usually called sitemap.xml, that lists your important URLs along with metadata like the last modification date. It does not guarantee indexation, but it makes discovery faster and cheaper for crawlers. For large sites, new sites with few backlinks, and sites with deep page structures, it is often the difference between a page being found in days or in months.
When the file contains errors, three bad things happen. First, you waste crawl budget: Googlebot spends its limited visits fetching 404 pages and redirect chains instead of your real content. Second, you create indexation gaps: pages that are not listed may never be discovered at all. Third, conflicting signals confuse the crawler. If your sitemap says a page is important but robots.txt blocks it, Google has to resolve the contradiction, and it usually resolves it by ignoring the page. A decent seo website checker flags these conflicts automatically, but I still verify them manually so I understand what is actually happening.
The Most Common XML Sitemap Errors
Across dozens of audits I keep seeing the same mistakes. On older properties I also take a moment to check domain age, because legacy sites tend to accumulate sitemap problems nobody remembers creating. Here is the full lineup:
| Error | What it means | Severity |
| 404 URLs in sitemap | Lists pages that no longer exist | High |
| Redirected URLs | Listed URLs bounce through redirects | High |
| Blocked URLs | URLs disallowed in robots.txt or tagged noindex | High |
| Wrong protocol or domain | Mixes http and https, or www and non-www | High |
| Non-canonical URLs | Listed URL canonicalizes to a different URL | Medium |
| Stale lastmod dates | Last-modified timestamps never updated | Medium |
| Malformed XML | Broken tags or bad characters that stop parsers | Critical |
| Sitemap not referenced | Robots.txt never points to the sitemap | Medium |
Malformed XML is the one error that breaks everything at once. If the file does not parse, search engines treat the whole sitemap as unreadable, which is the same as not having one. I once saw a single unescaped ampersand knock out a 20,000-URL sitemap for months. The owner only noticed when a routine seo score check showed his indexed page count collapsing. That is why validation is always step one.
How to Check XML Sitemap Errors Step by Step
This is my exact workflow. Follow the four steps in order and you will catch every error in the table above.
Step 1: Locate Your Sitemap URL
Try the two standard locations first: yourdomain.com/sitemap.xml and yourdomain.com/sitemap_index.xml. If neither loads, check your robots.txt file, which normally contains a line like “Sitemap: https://yourdomain.com/sitemap.xml”. WordPress SEO plugins generate the sitemap automatically and link it in robots.txt. If you run an seo page checker on the homepage, it will usually detect the sitemap URL as part of the technical scan. Note whether it is a single sitemap or an index of several child sitemaps.
Step 2: Run a Validation Scan
Open the sitemap URL in your browser and look at the raw file. Then run it through a validator. I start every audit by pasting the URL into our free sitemap checker, which fetches the file and reports broken links, redirects, and blocked URLs in one pass. Then paste the same URL into Google Search Console under Sitemaps to see what Google itself reports: submission errors, “couldn’t fetch” warnings, and indexed-versus-submitted counts. If Search Console cannot fetch the file but your browser loads it fine, a server or firewall rule is probably blocking Googlebot.
Step 3: Cross-Check the Sitemap Against Your Actual Pages
A validator tells you whether the listed URLs are healthy, but it cannot tell you whether the sitemap is complete. Export your real URL list from your CMS or a crawler, then compare it against the sitemap. Look for two problems: important pages missing from the sitemap (the 340 missing products from my opening story), and sitemap URLs that should never have been there, like tag archives, staging URLs, and old campaign pages. Every entry should be a page you actively want indexed.
Step 4: Confirm the Robots.txt Reference
Verify that robots.txt points to the correct sitemap and does not block anything the sitemap lists. Fetch yourdomain.com/robots.txt and confirm the Sitemap directive uses the exact, current URL. Then scan the Disallow rules against your sitemap entries. A classic mess: the sitemap lists the entire blog, but robots.txt disallows the /blog/ directory because of a forgotten staging setup. Run your domain through a robots.txt checker that parses the rules and tests sample URLs against them, then fix any conflicts you find.
How to Fix the Errors You Find
Remove dead and redirected URLs first. Delete every 404 and 3xx URL from the sitemap, or better, regenerate the sitemap from your CMS so it only includes live pages. If a removed URL still gets traffic or has backlinks, set up a proper 301 redirect to the closest live page first, then drop it from the sitemap. Always list the final destination URL, never a redirect.
For every sitemap URL blocked by robots.txt or tagged noindex, decide: either the page should be indexed (remove the block) or it should not (remove it from the sitemap). The same rule applies to canonical conflicts: the sitemap must list the canonical URL, never a duplicate that canonicalizes elsewhere. Fix protocol and domain mismatches by picking one version of your site and making the sitemap, canonical tags, and internal links all agree.
Repair the file itself. Fix malformed XML by validating after every edit; most XML errors come from unescaped special characters in URLs. Keep lastmod dates honest by updating them when content genuinely changes. If you exceed the 50,000 URL or 50MB limit, split the sitemap into smaller files under a sitemap index. Make sure the server sends the correct content type (application/xml or text/xml).
Resubmit and measure. Once the file is clean, resubmit it in Google Search Console and watch the indexed-versus-submitted counts over the next two to four weeks. This is the right moment to check SEO ranking movement for your target keywords, because cleaned-up crawl paths often show up as ranking gains before traffic. To check website seo ranking shifts tied to the resubmit, compare average positions before and after, since I check seo rankings weekly after a sitemap overhaul. When you check seo ranking of website pages that were missing from the old sitemap, expect the biggest wins there, since Google is discovering those pages properly for the first time.
FAQs
How often should I check my XML sitemap for errors?
Validate once a month and cross-check against your real pages every quarter. Also check immediately after any site migration, redesign, CMS change, or bulk content import.
Does a broken sitemap hurt my Google rankings directly?
Not as a direct penalty. It hurts indirectly: pages go undiscovered, crawl budget is wasted on dead URLs, and conflicting signals slow indexation. Fix the sitemap and rankings improve because Google can finally see and evaluate your best pages.
Should my sitemap include every page on my site?
No. Include only pages you want indexed: important content, product, and category pages. Leave out tag archives, utility pages, login pages, and anything tagged noindex. A smaller, accurate sitemap beats a large, sloppy one.
Why does Search Console say “couldn’t fetch” for my sitemap?
The usual causes are a server blocking Googlebot, a firewall treating the fetch as suspicious, a wrong content type, or an error returned only for certain user agents. Check your server logs and confirm the file returns a clean 200 status.
Can I have more than one sitemap?
Yes. Large sites use a sitemap index file referencing multiple child sitemaps, often split by content type: posts, pages, products, images. Each child sitemap must respect the 50,000 URL and 50MB limits, and the index file must be submitted or referenced in robots.txt.
Do I still need a sitemap if my internal linking is excellent?
Yes. Good internal linking helps enormously, but a sitemap acts as a safety net for orphaned pages, speeds up discovery of new content, and provides the lastmod signal that links cannot. It costs nothing to maintain once your CMS generates it automatically.
Final Thoughts
Checking XML sitemap errors is one of the highest-return technical SEO tasks you can do, precisely because so few site owners bother with it. Locate the file, validate it, cross-check it against your real pages, and confirm the robots.txt reference. Then fix what you find and resubmit. To go deeper into the format’s history and specification, the open Sitemap standard is well documented (read the full background on Wikipedia), and understanding it will make every future technical audit you run a little sharper.